The Slopocene
I think it’s safe to say that humanity has officially entered the slopocene.
The hype machine is in full swing. Almost daily new stories are published about how Large Language Models (LLMs, “generative AI”) are going to replace human labour. Vibe coders have fully joined the scene pumping out huge volumes of slopcode. Large corporate entities have started ripping off each other’s open-source software by rebuilding it from the ground up, using the suite of tests used to check the code is working properly to do so. Independent developers have even started reverse engineering proprietary software to provide a slop Adobe Creative Suite. People are increasingly turning to chatbots to do research. It’s easier to sift through yesterday’s regurgitated leftovers if it’s interactive and most search results are overrun by articles written by chatbots anyway. Almost every service you interact with is so excited to tell you about its new ai-assisted features.
AI musicians have made it into the charts. AI influencers are, well, influencing people. It’s being used to generate political slopaganda, and genuine news stories are oft accused of being slop. The debate around Artificial General Intelligence (AGI, frequently conflated with machine sentience) is still active, though is shifting toward whether we’re building Skynet and collectively writing our own death warrants. It seems to have a habit of coming up in every single conversation you have whether you like it or not. It’s inescapable.
Meanwhile the verdict is still out as to whether this is a new industrial revolution or a second 2008 financial crisis. Adoption has rapidly accelerated across the industry this year, the rise and fall of “tokenmaxxing” (company incentivised usage of LLMs and AI agents to automate workflows) has mostly passed. Bills are coming due on initial investments, and Anthropic has filed to sell shares on the public market. Usage is skyrocketing, but the actual ability of its usage to return an unambiguous profit is yet another debate.
What does this mean? Where is it going? Will the LLM bubble have popped before I finish writing this?
I don’t know, but I’m ready to have a guess. Apart from when the bubble pops, I’m not a betting man – though I’m sure it will.
There are only two futures for the current hype cycle that I really feel are worth discussing. One is if the hype bears out; the other is if the bubble bursts. By ‘burst’, I don’t necessarily mean a tidal wave of financial carnage, though that’s certainly possible, but I think that it is fairly uncontroversial to point out that a financial correction is very likely on the way or has already started.
I’ve indicated where I think this is going, so let’s start by looking at the other path.
As I am convinced that this path is a fiction, I present a short story to outline problems I don’t think we are prepared for should some of the crazier fantasies become reality.
The Desert Of The Real
It’s 2032.
OpenAI achieved Artificial General Intelligence five years ago.
2027:
The jobs crisis peaks, unemployment soars, AI companies represent a significant portion of the stock market. LLMs replacing human labour is largely responsible for the situation.
2028:
The achievement of AGI was ratified by a panel consisting of Geoffrey Hinton, Richard Dawkins, Karen Hao, Ed Zitron, Corey Doctorow and Elon Musk. They unanimously deemed GPT-7 capable of reasoning on par with a human. The company has petitioned the US government to confer the legal status of artificial person to the model. Doing so would give the company a legal obligation to keep GPT-7’s systems powered and running indefinitely or be charged with murder. The relationship between Microsoft and OpenAI is officially ended.
2029:
It is no longer possible to distinguish artificial “fake” media from the real thing. Digital information is no longer considered trustworthy unless directly transmitted between trusted parties or word of mouth. Reliable digital communications are only possible with people you have physically exchanged keys with. Anything not cryptographically signed is too easy to fake. Automated infrastructure delivers most digital goods and services.
2030:
The government barely exists. True power is exerted by a corporatocracy of service providers. With reality being impossible to verify outside of your immediate surroundings, politics becomes little more than reality TV. What’s real doesn’t really matter as long as the general population is provided for.
2031:
In a world with no labour there is a surprising dearth of leisure. Vocations are rare and previously skilled specialists are disappearing through atrophy. In person interaction fades and relationships that are easier to maintain, relationships with AI companions become commonplace. There is nothing to work toward or against.
2032:
Some people know who’s running the world these days, but not many. Societal inequality rivals that which was ended by the printing press. Most exist as little more than cattle. They want for nothing, their minds gently coerced by an unending stream of content individually tailored to keep each docile. Occasionally you see people who seem to know what is going on but you never meet them. You can barely tell the difference between reality and your content feed. You hear people have started uploading their consciousness in order to live forever. You don’t think you could tell if they’d done it to you already or not.
There is no social contract. There is no society. There is just an endless desert of consumption, an ouroboros of regurgitate.
Dystopia Now
Of course, I’m not a prophet. Maybe AI really does revolutionise everything and we end up living in a post-work fully automated luxury communist dream society. However I don’t think we’re prepared at any level for that eventuality, and anyone who thinks we are lives in a pretty big ivory tower.
Every truly utopian vision of a future with AI relies on either a benevolent dictator or equity of ownership and control. We have neither. I would argue that accommodating any kind of dictator is ceding too much control; especially when concerning the future of truth itself. My little story may have been hyperbolic, but the ramifications aren’t. Ownership of the infrastructure is a problem now. Its impact on society is a problem now. Its impact on our self expression is a problem now.
Increasingly we are excluded from control of our own lives or how they are governed. In an age of media driven by social algorithms this is becoming a problem for our private leisure too. When creatives are forced to compete with slop, their output trends toward slop too. I’ve already written about how the structure created by this system rewards trends toward the homogenised and/or derivative.
This scenario creates an environment that pushes people toward low effort, low quality work that erodes skill. It also floods the zone whilst maintaining audience capture. It creates a vicious feedback loop of “if you can’t beat them, join them”. Why put effort into something when people are rewarded for laziness? People using algorithms to create material to appeal to algorithms that are designed to make people act more legibly to algorithms.
These forces already act on us, parts of this dystopia are already quite real.
The construction, training and running of these massive frontier systems is ultimately an unprecedented siphoning of collectively produced public information, provided for free at point of access, into private hands. It feels like an attempt to enshittify the institutions of learning themselves. Of course the original information is still out there on the internet for the most part, but the success of LLMs disincentivises those who innovate without, and blinkers those who create with. A statistical model trends toward preexisting patterns – they exist explicitly to identify them. This pattern predates LLMs, but they put booster rockets on this pattern, something else I’ve also written about at length.
So why do I think it’s so likely that the bubble will pop? I think it’s worth addressing before looking at what might happen afterwards.
The Singularitopalypse
One thing the hype cycle has relied on historically is the narrative on continuous growth: that the models will just keep getting smarter, that we just need to keep training better models. Even the shouting about a ‘pause’ feels like it’s couched in the dynamics of a Mexican standoff. Like a nuclear non-proliferation treaty the words are cheap to say, but harder to act on – and rely on the trust that the other parties will actually stop. These companies owe their future to having an edge. All the good will in the world won’t stop them trying to retain it. But this narrative of growth has a central problem that has slowly become louder over the last few years: how is this achieved?
Companies started with a massive corpus of questionably obtained information from the public internet – a massive amount of training data. They mined large communities of open source code (especially GitHub). Now they use the data you feed them whilst interacting with them, and use a combination of techniques to attempt to refine the information they already have. They may assure you that your sessions are private, but you only need to look at how surveillance capitalism is used with ‘anonymous’ data to understand how these rules can be bent and broken. Even if they say in their legals they don’t use what you work on for training, I wouldn’t trust it.
The issue is that, as with many areas, the 80/20 rule seems to ring true. The initial progress is comparatively easy to achieve, but over time the amount of effort required for continued improvement gets progressively harder. The free easy data to obtain has already been mined, by this point (discounting destroying books to continue training). The amount of training compute to create these improvements has been growing by a factor of around four to five year on year since 2020. Synthetic data – that is, LLM output created for use as new training input – has been one answer. These refinement and recursive techniques can have real utility, but without careful utilisation the risk is that training models on slop can lead to a form of “AI Alzheimer’s” called model collapse.
The upshot of all of this comes back to the 80/20 rule. Progress is getting harder to pursue and only more so over time. The narrative of the AI bubble and the singularity – where AI outperforms people on every level – is cut from a similar cloth in terms of the conversation around inevitability. And both arguments tend to have a similar public perception – that of the extreme fantasist.
Even if AI superiority has taken a back seat in recent months, the industry sprang from this vision. Major players still believe it, and a lot of money is riding on it. And even if the systems that have been created as a result have some utility, there are some major issues with the financial model being used to drive it. One that is a major threat to the companies building these absolutely massive, expensive models. Infinite growth is never guaranteed, infinite change, at least until the heat death of the universe, is assured.
Sloponomics
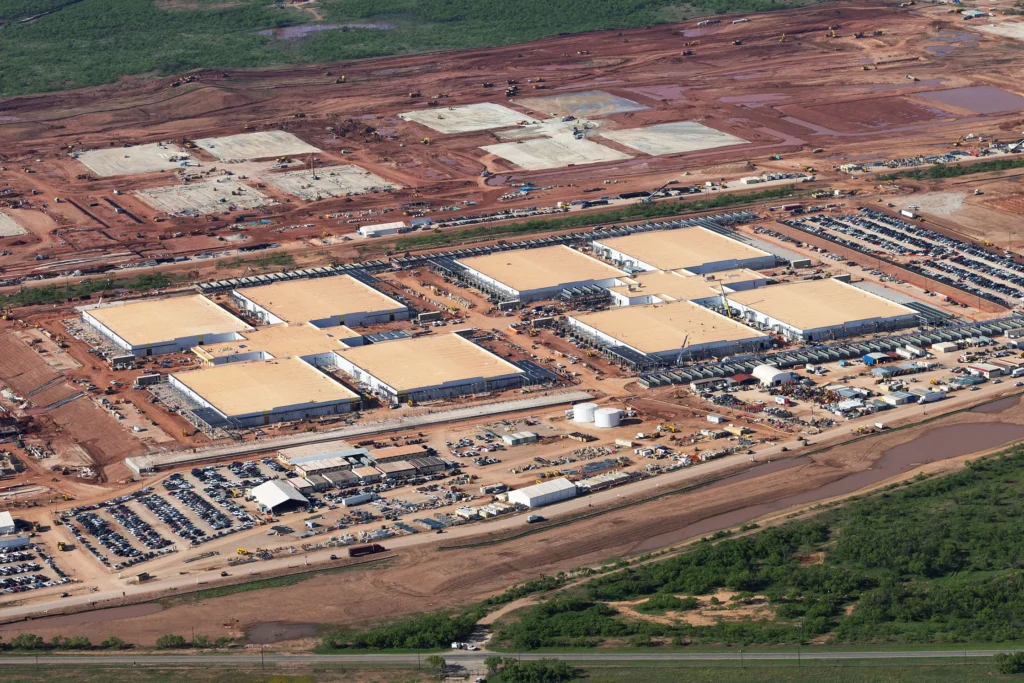
Everything that has taken us to this point has required massive amounts of infrastructure spending and financial investment. At time of writing, AI-related spending across the economy is projected to total $2.7 trillion by the end of the year. Market penetration is, as previously discussed, incredible. You can’t get away from something being presented to you via an LLM in some way. It is one of the most rapidly adopted technologies of all time – faster than the internet or the personal computer. These arguments are published online with breathless reverence, but it’s worth looking a little closer at what this means for the AI economy. The dominant narrative is of a hyperjump into the future. A new frontier in ascendance, a second industrial revolution, a reinvention of the capability of humanity.
I think it’s important to take into account what the ‘AI economy’ actually is, how it interacts with industry and how we choose to measure that impact.
I am not about to argue that people “don’t really use AI” or that it has no utility. In an exhausted, time-strapped world, these language engines have become a truly useful way of automating busywork. But part of the reason for such massive penetration is how unavoidable using it is – and free at the point of use. The top use cases I see for the consumer are effectively as an alternative to a search engine, a counsellor/confidant, or an automated word processor. Tasks that aren’t hard but, like with most SaaS platforms, are aided by this extra layer. But the companies that run, host and build these models have real bills that need paying, and are really struggling with profitability of frontier AI.
Amazon is desperately buying so many GPUs that it can’t turn them all on, hardware that is notorious for rapid depreciation as new generations are manufactured. Until the data centre construction and power demand complications are resolved, none of it can make money for them. The finances aren’t looking great. Not to mention the circular financing arrangements that appear to be rife across the industry. The question becomes “when will some money enter from outside the system?”.
As mentioned, a large portion of the end users of LLM providers don’t pay for them. If they do they’re bundled as an add-on for a pre-existing service. A significant portion of the hyperscaler’s (Google, Meta, Microsoft, etc) AI-related income comes from other AI companies using their resources. Moreover, the risk concentration in the US stock market greatly weighs on these companies, with them taking a large share of responsibility for current trends. This shelters the end user from the true cost of the service they’re using, and many of them are unlikely to pay for something that, in general, has a mild impact on their day – casually or professionally. It’s potentially a lot of embedded chatbots suddenly not justifying their cost.
Combine this with increasing pressure on companies like OpenAI and Anthropic to turn real profits that come from outside of the industry and the outlook doesn’t look fantastic.
The ubiquity of LLMs isn’t necessarily an indicator of their indispensability. Neither is their utility. An ice cream machine can be useful, but price can make owning one unjustifiable. So-called ‘narrow’ models trained for specialist tasks (for example, Microsoft’s Phi-4 model, a ‘Small Language Model’ geared toward reasoning and mathematics – more on that later) can be good at specific jobs. This is a lot closer to how classical machine learning is used, but these small models won’t command the kind of revenues needed to justify the continued operation of these companies in this way.
And when(?) the bubble pops, these forces won’t disappear overnight. Pandora’s box has been opened.
Once You Pop You Can’t Just Stop
As the finances start to wobble, as they already seem to be doing in China, I expect the first consequence to be a tightening of training budgets. Distillation, synthetic data and specialisation will all get a higher focus. Microsoft’s Phi-4 is a good example of this: a model trained on carefully curated mixes of synthetic and ‘organic’ data with the goal of providing greater reasoning and problem-solving capabilities with a smaller footprint. Synthetic data has proven especially useful for this, but the kinds of generalist intelligence we’ve been taught to expect from ChatGPT are the ones that are particularly dependent on diverse inputs. Repeated training on LLM outputs risks model collapse, and even with models trained mainly on synthetic data there still seems to be a general level of reliance on ‘organic’ human-created material.
On the consumer end, the very first thing that will (and has already started to) happen is that LLMs will get more expensive to use, especially for the flagship models. There is good and bad in this. On the positive side, many redundancies will need to be reversed. The collapse in demand for high-quality computer parts is likely to reduce the price of consumer electronics, games consoles and PCs. A welcome change indeed considering the direction the market is currently headed. Also it hopefully means that made-up skills that no one can quantify become less important on CVs, as companies run out of money to throw at Synthetic Text Extruders (a more accurate description of an LLM) and can’t give their employees unlimited free access. Sanity might start to prevail somewhat. I’m sure that, as costs go up, “prompt engineering” – the art of knowing how to whisper to an LLM in the right way to get it to do what you want – will become a more valued skill, but in a narrow niche.
As prices go up, people will be looking to save costs and focus on smaller, more efficient models. There will be a focus on self-hosting setups that are cheaper to run, which will also likely create a convenient demand for more powerful consumer electronics. Whether this will be justification enough to keep all prices high remains to be seen. It would, of course, depend on the perceived value of a smaller, less powerful version of something you used to get for free. My guess would be that specialising these models for more narrowly defined tasks (so-called “thin” AI) will give them a veneer of improvement to make them desirable. How fit for purpose this will be will come down to use case. More innocuous, natural language processing stuff could work quite well. Therapy chatbots and medical diagnosis apps will likely be very damaging.
Now the models are real things that exist, they are unlikely to go away. Expensive to use and limited access maybe, but if they provide real tangible benefits then they will be used by people with the resources to do so. Economically, I’m not certain the gains will be completely justified for most applications. I’m sure there’s a decent chance that a company like Palantir might survive. Flimsily justified murder feels like something you can make budgetary justifications for as a government. Usage as human decision accelerators is probably the most damaging application they can be put to. It provides ample opportunity for systemically ingrained bias to tip the scales in situations where the system often wants you to make unethical decisions to save money. Things like denying healthcare and insurance claims, access to benefits, legal decisions. I can see a world where these LLM services are used by the largest private entities to grease bureaucratic wheels using data science. The question really becomes how far into the weeds does this technology retreat? How do you avoid being stuck on an automated customer service call that never ends, where there is never a human to talk to on the other end? YouTube is already there. Balancing the equation of value to cost for these services is going to have a massive influence on the way this paradigm shifts.
Speaking of social media, I don’t think we’ve reached the end of the slopocene just yet. Attention farming and faked propaganda media are plenty valuable. I wouldn’t be surprised if nefarious organisations and / or governments manage to make the space on their balance sheets to pay for premium slop generation.
Sloppy Seconds
For years we’ve been told that “AI is coming to take our jobs”. It has become a meme:
“I want AI to do my laundry and dishes so that I can do art and writing, not for AI to do my art and writing so that I can do my laundry and dishes.” @AuthorJMac
The intended goal from the beginning of this cycle was to make human labour redundant, or, if that isn’t possible, to at least markedly reduce its value. Benn Jordan calls this “Leveragism”: the combined effort to reduce the value of everyone’s paycheque just enough to keep the majority in the rat race, fighting to tread water and keep their stability. Too exhausted or too scared to resist or make meaningful change. These companies also invest huge amounts in lobbying funds, making it difficult to resist in a democratic way.
They want us poor. They need us poor. I would look very carefully at those opposing wealth taxes and what their motivations may be. Musk recently, briefly, was the world’s first trillionaire.
Whilst RAM, disk storage, and hardware prices are likely to go down after the bubble pops, the decline will, in all likelihood, be anything but instant. If suppliers have thought ahead, they may well artificially restrict production or build expensive new infrastructure to keep prices high.
Worldwide, insane amounts of cash are being funnelled into constructing data centres. If demand were to suddenly collapse, a lot of people would find they weren’t getting the revenue they expected. With people invested so deeply, it wouldn’t be that surprising if it triggered a new 2008-style recession.
In a way, it feels like corporate finance is trying to destroy the state. Destroying the economy will likely cause even more privatisation, as public funds get slashed to support a crumbling system. If inequality isn’t addressed as a matter of urgency, then it’s quite possible this kind of “leveragism” ends in a modern equivalent of feudalism. The Wayland-Yutani style future that Alien presents us with: a world where people are owned by corporations and work to pay off their debt. My personal theory is that AI companies are trying to scare governments into nationalising them. Doing so would give the current owners a way out, leaving a huge amount of debt on the shoulders of public institutions. There are details in Anthropic’s IPO filings that allow existing investors to cash out. Their own filings disclose around $900 billion they’ve committed to spending on compute and infrastructure, much of it years before it becomes operational. Some of that may be conditional, but these are very large numbers.
The public could be left holding the bag, paying for it with tax money, pushing the state back into austerity measures. Things are bleak out there, but if the state does crumble we owe it to each other to reject corporate dominion as an alternative.
Poisoning The Well
The one thing LLMs have managed to do with worrying efficiency is to completely conquer The Discourse. LLMs are like that one uncle with the worrying political afflictions who turns up at every family gathering. They’re incredible at turning up in conversations and making you have opinions about them. It’s become almost impossible to have a normal conversation that doesn’t mention the eldritch horror you can outsource your thinking to. I’m hoping that once the bubble pops we can all, collectively, stop fucking discussing this shit. Let’s hope it fades into obscurity like crypto discourse.
I’m hoping, no matter what happens, we are collectively freed from talking about it. In my mind, what this technology represents, more than anything else, is one of the biggest knowledge transfers in human history. Access to good information is increasingly complicated by LLMs, and those creating it have less incentive to keep going because they are competing with slop. It then harbours all of this information behind an inevitable paywall.
As a programmer, there is a great pathos wrapped up in watching a discipline I taught myself using open-source software and free learning resources be dominated by this. The very openness of the industry created a vast dataset that made it an uncannily apt target for automation. I can’t help but feel that large corporations took note of a group of powerful workers and saw a unique opportunity to steal their labour and give them a front-row seat at the slop factory.
As an amateur philosopher, I don’t think we’re psychologically prepared for the technology. The human mind has evolved to anthropomorphise and empathise. LLMs are a brain hack – by talking ‘like people’ the very act of communicating with them forces us to treat them like people. There is no way of doing so without being manipulated on some level. Relying on one to rationalise your own thoughts is to throw your cognition into the hands of an averaging machine. You will always be trended toward a median position. It may not feel like it but innovation dies here. And I say this as someone so exhausted by the discourse that I’ve been sitting on this article for coming on two years. Hell, I even used ChatGPT as an editorial consultant because I was so burned out – and had to fight the entire way to write the article I wanted to publish, rather than another smug, centrist take. I have no doubt that a real, human editor would have made this piece substantially better.
As an artist and writer, the technology feels like a loophole for fair use. It is an ‘ethical’ plagiarism machine that allows you to claim innocence because the input has been ground down to such a fine powder as to be unidentifiable. Fair use and copyright haven’t been designed for this. Not that I’m that much of a fan of copyright – it always asymmetrically supports the person with the most money. But this technology does not create novel ideas – not in my opinion – because I believe that requires consciousness and cognition. There are no new ideas, but that doesn’t mean all ideas are just re-assemblages of old ones.
If my next article is another critique of LLMs I think I’m going to scream.
Or maybe I can have a good chuckle about the “Magnificent 7” when they end up choking on it. I doubt that anyone’s going to burn to the ground but maybe there will be a black eye or two to go around.
In any case, one critical part of circumventing the deleterious effects these text extruders excrete is the death of the hype cycle. Hopefully there will be some breathing room for building solutions and fewer debates around the eye-watering energy costs of all these data centres dedicated to running black-box, general-purpose problem-solving machines.